NIFTY 50 Stock Price Prediction using LSTM and Flask: AI Final Year Project with Source Code
49 trained LSTM models, 21 years of NIFTY 50 data, and a dark-mode Flask dashboard that forecasts tomorrow’s closing price. An AI final year project you can demo the day you download it.
Technology Used
Python | TensorFlow (Keras LSTM) | Flask | Pandas | NumPy | scikit-learn | Plotly.js | Bootstrap 5.3 | Waitress | Jupyter Notebook
Abstract
This project trains a separate LSTM deep learning model for each of 49 NIFTY 50 stocks, using daily price data from 2000 to 2021, and predicts each stock's next trading day closing price. Every model looks at a 60-day window of prices plus 18 engineered features, including SMA, EMA, RSI, MACD, Bollinger Bands and lagged closing prices. The trained models are served through a Flask web app with interactive Plotly charts, a backtest view, an up/down forecast card with a confidence gauge, and a feature that lets you rewind the prediction to any past date to see what the model would have said back then.
It's built as an educational project. The point is to show the complete time-series ML workflow on real Indian market data, not to tell anyone what to buy.
What This Project Actually Does
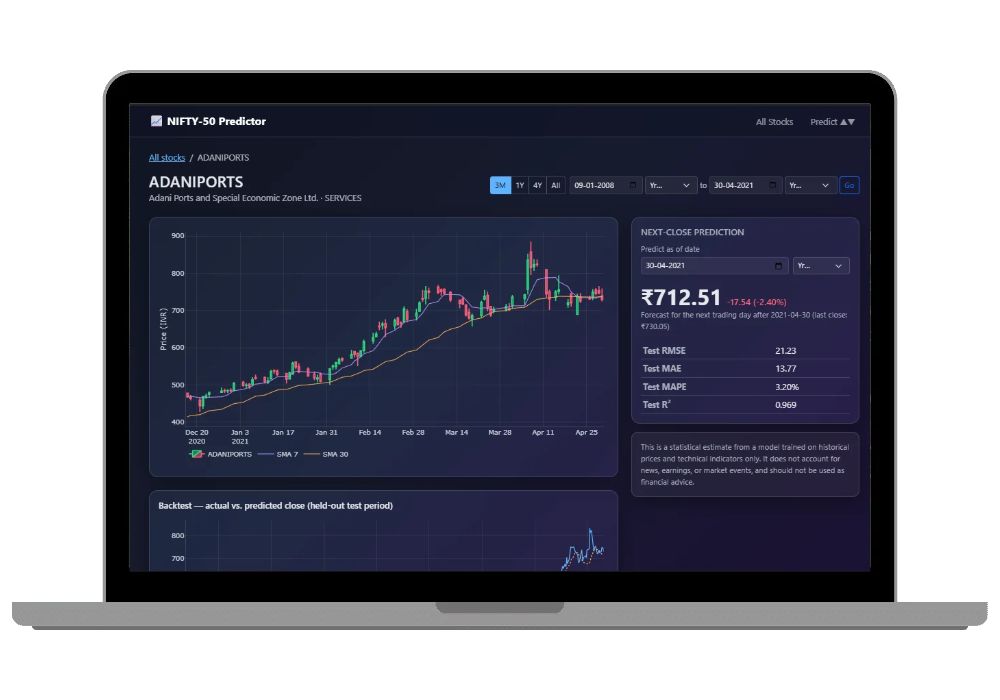
You open the website. You see a grid of 49 NIFTY 50 companies, like Reliance, TCS, HDFC Bank and Infosys, with their industry listed. Click one and you get a candlestick chart of its full price history, with moving averages drawn on top.
Then the interesting part. The app shows you what its LSTM model thinks tomorrow's closing price will be, whether that's up or down, and how accurate the model was on data it never saw during training. You also get a chart where the actual prices and the model's predictions sit on top of each other, so you can see exactly where it got things right and where it drifted.
And there's a "predict as of" date picker. Pick any date, say 14 March 2015, and the app tells you what the model would have forecast for 16 March. Examiners love this, because you can show them a prediction and then show them what really happened.
Key Features
Machine Learning Side
- One LSTM model per stock: 49 trained
.kerasfiles already sitting in themodels/folder, each with its own scaler and config JSON. No retraining needed to run the app. - 18 input features per day: Open, High, Low, Close, VWAP, Volume, SMA_7, SMA_30, EMA_10, RSI_14, MACD, MACD_Signal, BB_Upper, BB_Lower, and closing price lags of 1, 2, 3 and 5 days.
- An 85/15 chronological train/test split with no shuffling, so the model never peeks at future data. This is the detail that separates a correct stock project from a broken one, and your external examiner might actually ask about it.
- Two Jupyter notebooks:
stock_price_prediction.ipynbfor a deep dive into a single stock (you change oneSYMBOLvariable), andtrain_all_stocks.ipynb, which retrains all stocks in one go and writes RMSE, MAE, MAPE and R² for each into_training_summary.csv.
Web App Side
- A searchable stock gallery at
/. Type "bank" and the list filters as you type. - A stock detail page at
/stock/RELIANCE(or any symbol) with a candlestick chart, preset ranges for 3M, 1Y, 4Y and All, and a custom from/to date range. There's also a year-jump dropdown, so you don't have to click back through 20 years in a date picker. - A backtest chart of actual vs. predicted closing prices on the held-out test period.
- A
/predictpage with the up/down forecast, expected price change, a forecast chart and a confidence gauge based on the model's test-set R². - A dark glassmorphism UI built on Bootstrap 5.3: frosted-glass cards, a see-through navbar, and charts styled for dark mode. It looks good on a projector.
- A JSON API under
/api/with five endpoints: symbols, date range, history, predict and backtest. You can call them from Postman during your viva if someone wants proof the backend is real. - A
/healthzendpoint that reports how many models are loaded, and a production server (wsgi.py) that runs on Waitress, which works on Windows, unlike gunicorn.
How the Prediction Pipeline Works
Raw CSV goes in, and the code in webapp/ml/features.py computes the indicators exactly the way the training notebook did. MinMaxScaler squashes everything to the 0–1 range. The last 60 days become one input sequence. The LSTM outputs a scaled number, the scaler inverts it back to rupees, and that's your predicted close. PredictorRegistry loads each model the first time someone requests that stock and keeps it cached after that.
The folder structure is clean, too. There's an app factory in webapp/__init__.py, separate routes/main.py and routes/api.py, and development and production configs. So when your guide asks you to explain the architecture, you're explaining something sensible.
Real-World Applications
- A teaching demo for anyone learning time-series forecasting on real data instead of the airline passengers dataset everyone has already seen.
- A backtesting sandbox where you compare how well a technical-indicator model does on Infosys vs. Coal India across different years.
- A starting point for a fintech dashboard. Swap in a new model or add sentiment from news headlines, and the Flask + Plotly frontend still works.
- A data API for other tools. Scripts or a mobile app can pull OHLCV history and predictions from the
/apiroutes.
The Honest Part
Here's the thing. What's genuinely hard about this project is understanding why the feature engineering in the notebook and in features.py must match exactly. Change a window size in one place and forget the other, and the model gets fed garbage without throwing a single error. Spend 30 minutes reading both files side by side before your viva.
But the part that looks scary, training 49 deep learning models, is already done for you. The models ship pre-trained. You install the requirements, run python run.py, and the dashboard is live.
One more honest point. A few stocks, including COALINDIA, ONGC, NESTLEIND and BAJAJFINSV, have weak or negative R² on the test set. That's not a bug. Price-only models can't see news, earnings or policy changes. Mention this limitation in your report's future scope section and you'll look smarter than students who claim 99% accuracy.
Who Should Buy This
If you're a student who needs a working project for your college submission, final year project, semester project, internship or academic demonstration, this is for you. Whether you're studying BCA, B.Tech, MCA, M.Tech, Computer Science, IT, AI, Data Science or another related field, you can choose a project that fits your requirements. If you need the source code, project report, documentation, or help setting up and running the project, CodeAj gives you the resources and support to get started faster.
It's an especially good fit if your guide wants deep learning (not just a scikit-learn regression) and you'd like a topic that sounds impressive without needing a GPU or any paid API.
Why CodeAj
You get the complete source code, both notebooks, the dataset, all 49 trained models, and a project report you can adapt to your college's format. If something breaks on your laptop, like a TensorFlow version clash or a port that's already in use, our team will get on a call and help you set it up. If you want more options in the same space, browse our AI and ML final year projects, check the machine learning projects with source code, or look at other Flask final year projects if your college prefers Flask-based submissions.
Disclaimer
This is a research and educational project. The forecasts are not financial advice and shouldn't be used for real trading decisions.
Frequently Asked Questions
Extra Add-Ons Available – Elevate Your Project
Add any of these professional upgrades to save time and impress your evaluators.
Live 1-on-1 Mentorship
Personal session with an expert developer
Project Setup
We'll install and configure the project on your PC via remote session (Google Meet, Zoom, or AnyDesk).
Source Code Explanation
1-hour live session to explain logic, flow, database design, and key features.
Want to know exactly how the setup works? Review our detailed step-by-step process before scheduling your session.
₹999
Custom Documents (College-Tailored)
- Custom Project Report: ₹1,500
- Custom Research Paper: ₹1,000
- Custom PPT: ₹800
Fully customized to match your college format, guidelines, and submission standards.
Project Modification
Need feature changes, UI updates, or new features added?
Charges vary based on complexity.
We'll review your request and provide a clear quote before starting work.
Project Files
 Reviews
What Our Students Say
He explained the project clearly and thoroughly. He was very supportive throughout the process and was always available to help when needed. His guidance and assistance made it easier to understand the project and complete tasks effectively.
I had a very good experience with CodeAj Marketplace. The team is professional and supportive, especially Ajay Pandit sir who guides clearly throughout the project. The work was completed neatly and according to requirements. A great place for learning and project development. Highly recommended for students and developers.
Excellent explanation! Concepts are explained in a very simple and understandable way. It really helped me a lot in improving my knowledge. Great work!
Codeaj was really helpful with my project, especially during the customization part. He didn't just do the work but also took the time to explain everything, from the project structure and database to the code itself. It was a huge help, especially for students trying to understand how everything fits together. I really appreciated his support and the way he made things easier to follow.
Working with CodeAj Marketplace has been such a positive experience. The projects delivered are original, carefully crafted from scratch, and tailored to meet expectations with impressive attention to detail. What really makes him stand out is his willingness to go the extra mile — not just in creating outstanding work, but also in helping others understand how everything functions. He explains things clearly, addresses questions patiently, and ensures the whole process feels like a learning journey instead of just a handover. On top of the technical expertise, his calm and approachable personality makes communication effortless. No unnecessary stress, just smooth collaboration and genuine support. I truly value the dedication he brings to his work and would highly recommend him to anyone in search of high-quality, authentic projects.
I purchased a project from him recently and I have to say it's one of the best decisions I've made. The project was absolutely beautiful, built completely from scratch with no shortcuts, and perfectly matched what I wanted. What makes him stand out is not just his ability to create anything we ask for, no matter how complex, but also the way he helps us understand every part of it. He patiently explains the process, clears doubts, and makes sure we actually learn from the project instead of just using it. On top of his skills, his personality is amazing — he's calm, chill, and very friendly to talk to. There's no stress when working with him, only smooth communication and genuine support. I truly appreciate the effort he puts in and would highly recommend him to anyone looking for original, high-quality projects.
I received my project from CodeAJ Marketplace on time, and the work was very neat and well-presented. The team maintained good communication and delivered everything as promised. I appreciate their timely completion and professional approach.
I sincerely thank Mr. Ajay Pandit for his constant support and valuable guidance throughout the project. His timely advice, encouragement, and expertise greatly contributed to the successful completion of the work. I'm truly grateful for his mentorship.
I had an outstanding experience with CodeAj while developing my mobile app. Their team was incredibly cooperative, ensuring every customization I requested was implemented flawlessly. The service was top-notch, and the final product exceeded my expectations. Highly recommend CodeAj for anyone seeking professional and reliable app development services! 11/10
I would like to sincerely thank Ajay Pandit for providing me with the project. His guidance and explanation of the system's architecture, modules, and AI integration were extremely helpful in understanding the project thoroughly. Ajay's support played a key role in helping me implement the hotel booking and payment module effectively. His willingness to clarify concepts and walk me through complex logic made the learning process smooth and insightful. I truly appreciate his mentorship and the time he dedicated to ensuring I was well-prepared for both the development and presentation of this project.
I had a great experience with the project I purchased. It was well-structured and met all my expectations. The team was responsive and supportive throughout, addressing all my queries promptly. Highly recommended for anyone looking for quality projects and good service.
I'm really thankful to Codeaj for helping me with my project explanation and guiding me throughout. Your support made everything much easier and clearer.
The project he made was wonderful, and the way he patiently listened, understood all my ideas and presented them so well in the project, was amazing. I would highly recommend him to everyone.
I would like to sincerely thank Ajay Pandit for providing me with the project. His guidance and explanation of the system's architecture, modules, and AI integration were extremely helpful in understanding the project thoroughly.
Too good experience, I love their projects and they are available for you to help, they are incredible good. Must avail their services. I am happy customer.
The team was very supportive and their explanation was very good, they are clarifying each and every doubts with lots of patience. Highly recommended for quality projects.
I really like their work and they made good project in less amount.
Thank you, CodeAj Bro, for supporting the Doctor Appointment System project. Your guidance during the project setup, installation, and report creation was very helpful and greatly appreciated.
One of the best Software Developer provide the best setup environment for project, good explain skills, and good technical skills, step by step explain project through google meet and budgetly price project Available.
Thank you so much for your excellent work on our project! Your kindness and clear explanations made the entire process smooth and enjoyable. Highly recommend!
Really very supportive, helpful and kind, loving nature. Available for any time for any query, highly recommend to get projects from him.
Awesome projects. They support on setting up the project after purchasing. Completely legal one. Affordable projects too.
Code AJ guide team are very formal, friendly to setup project step by step and explain each question 🙂
Thank you codeAj, Best site to get your project done quickly, with fast responses and instant clarification of any project-related doubts.
I really liked the work, and they solved my issues very well too.
They provide very good service and code also running condition and they fulfill all the queries it's very helpful.
Really helpful, makes things easy to understand and very kind nature, you can look forward to get help from here.
Thank you so much for building the Project for my requirement.
Looking forward to many many collaborations and always tend to buy the projects.
I am so satisfied with codeAJ because of his help.
Thank you so much sir for your support and help.
Ajay bro has excellent knowledge and his response is nice.
This is a great app I love it with good functionality.
Thank you so much for your help and support.
Highly recommended for the projects.
Loved the project work.
It is super for students.
I recently purchased this project online and I am very satisfied with it. The project was well-designed, properly organized, and included all the necessary files and documentation. The source code was clean, easy to understand, and worked as expected. A special appreciation for the project explanation and setup session. The session was detailed and easy to understand, covering both the project implementation and the complete setup process. All my questions were answered clearly, which helped me understand the project much better. Thanks for giving your time.